Accountability Before Harm: What "Ethical Review" Actually Requires
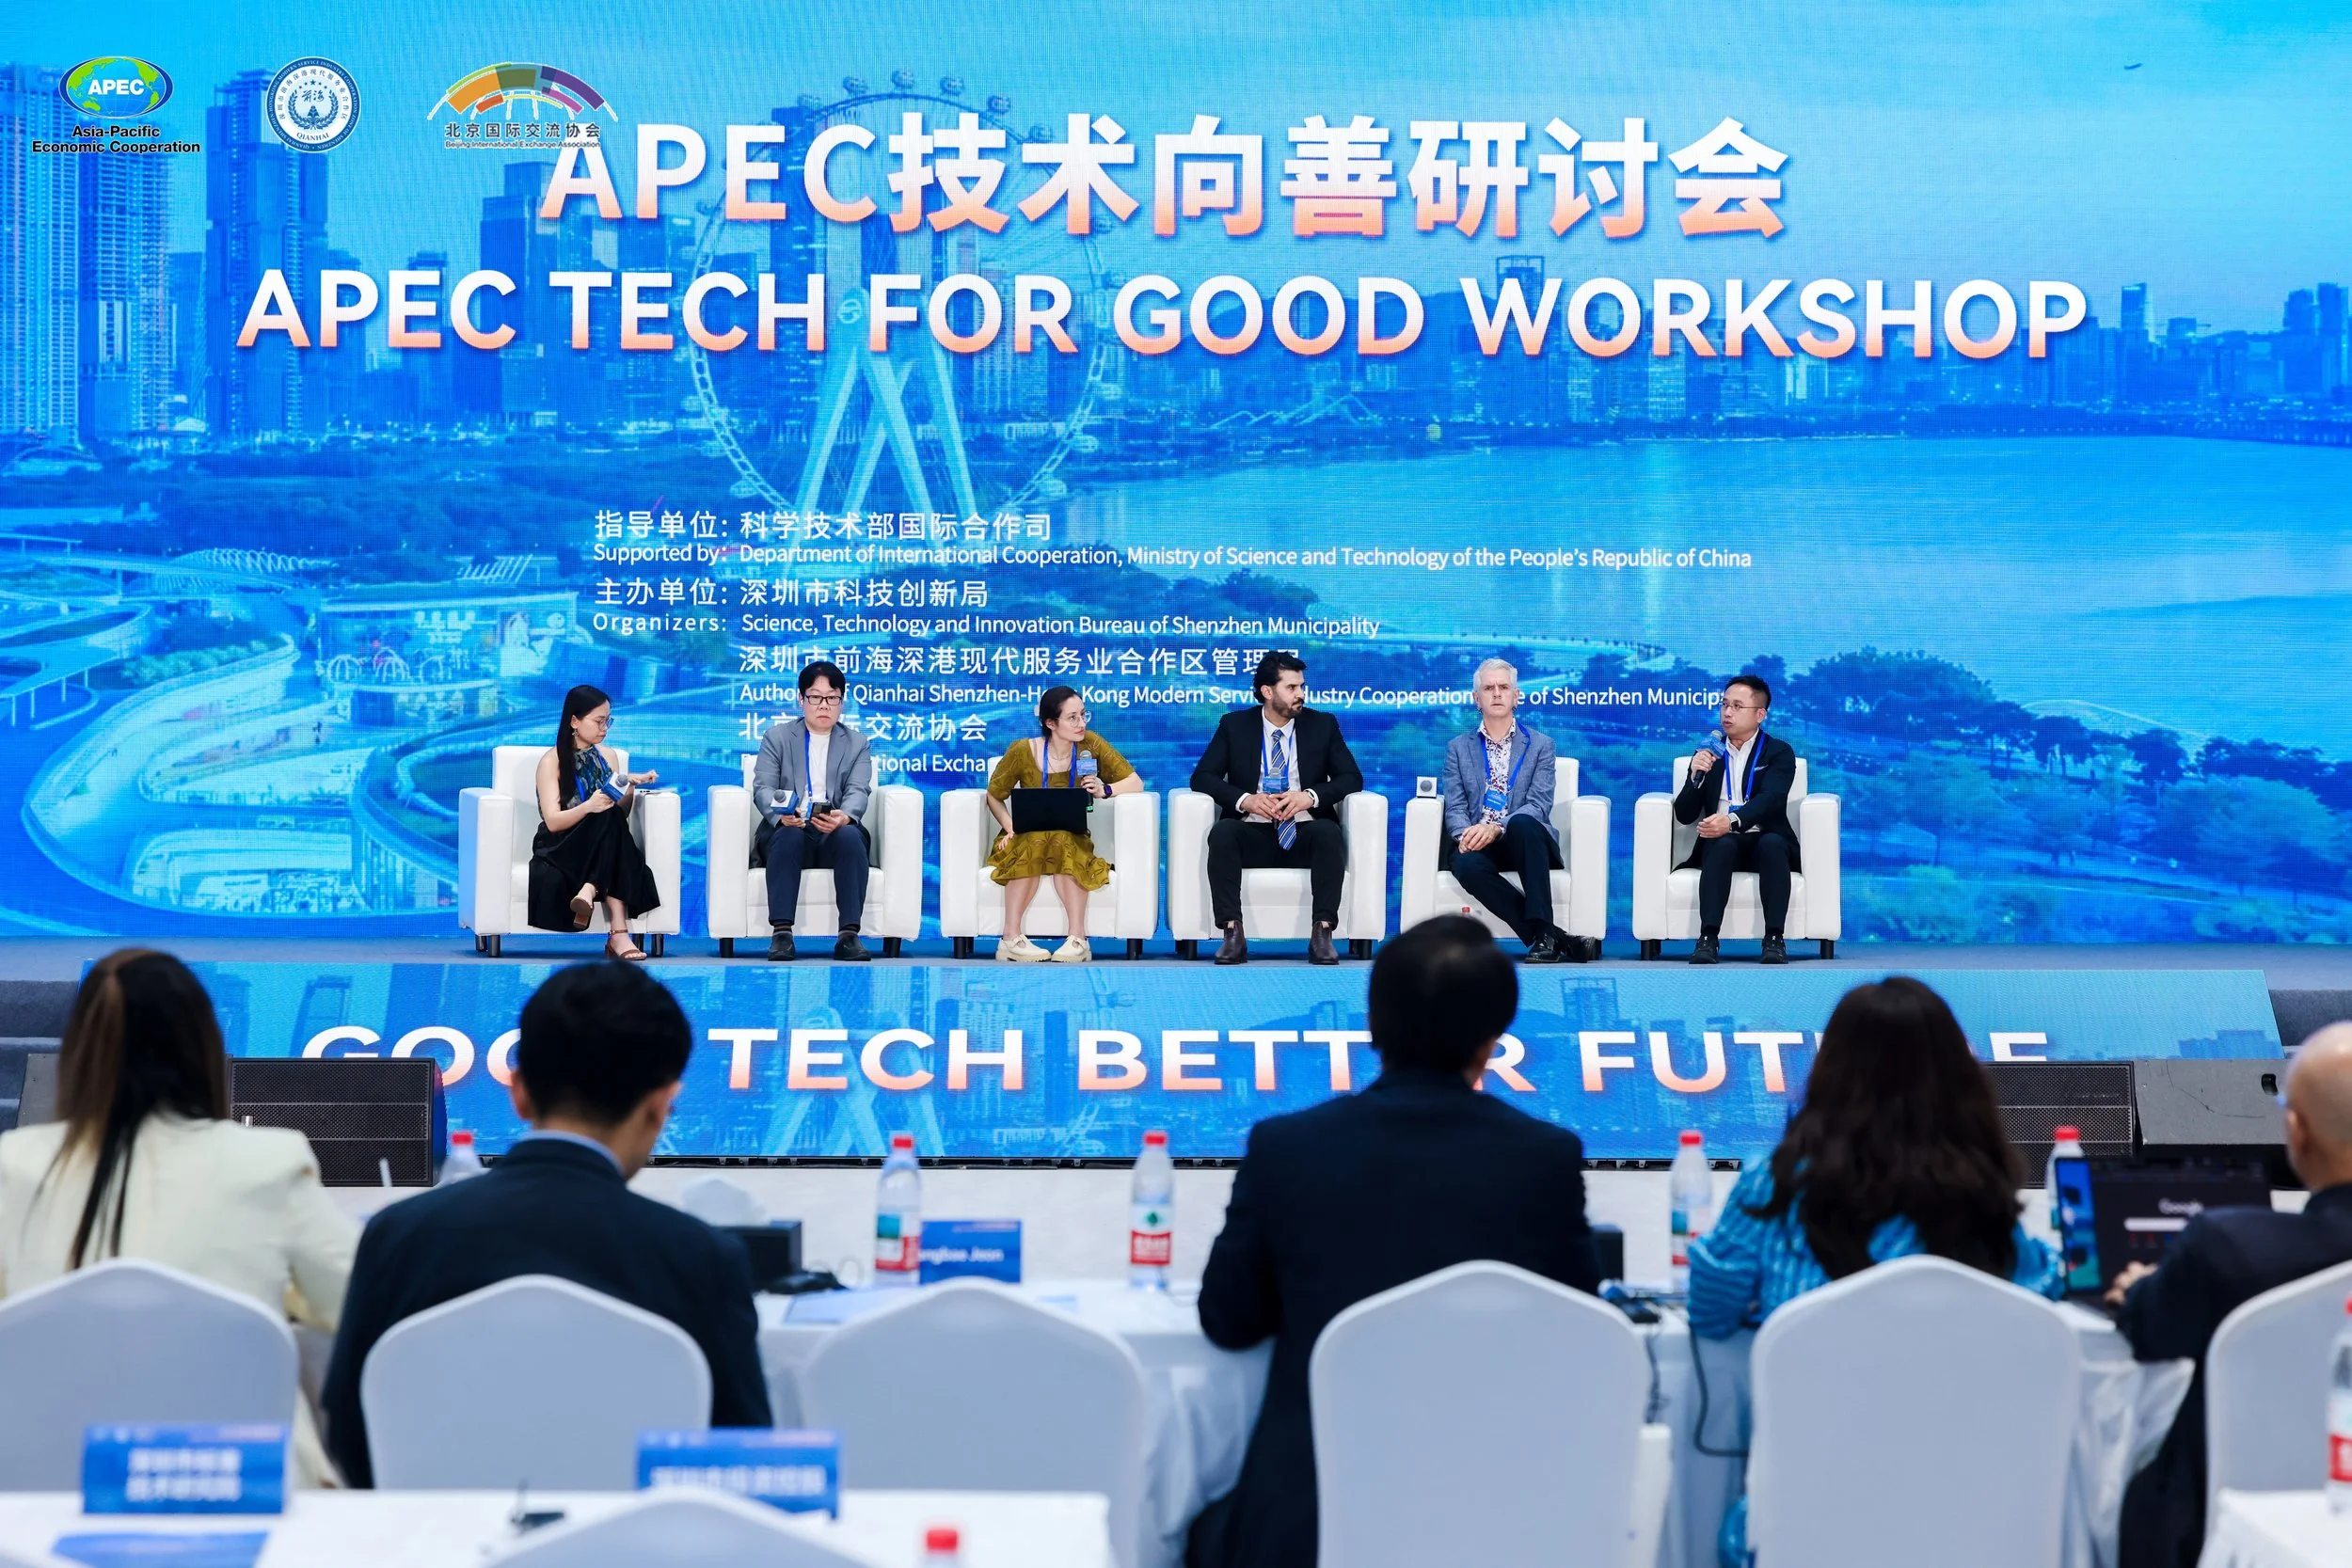
Session 3: Technology Moves Too Fast, Regulation Moves Too Slow: Can Ethical Review Apply the Brakes?
燊思想 — Dixon's Thoughts on AI, Ethics & Digital Rights · 15 min read
A business executive gets a video call from what looks and sounds exactly like a close friend, asking for urgent help with a business deal. He sees the face. He hears the voice. He transfers several hundred thousand dollars within minutes.
The "friend" was an AI-generated face-swap and voice clone.
I opened my session at the APEC Tech for Good Workshop in Shenzhen this July with that case, because it cuts through the abstraction that usually surrounds AI governance conversations. Everyone agrees AI needs ethics principles. Almost every major economy has published some version of them by now. But this case exposes the actual gap: the tools that made this scam possible were commercially available with no pre-deployment safeguard, and the guidance that might have prevented it arrived only years later, after the harm had already scaled. Every principle that could have stopped this existed on paper. None of them was attached to a moment that could actually stop it.
That's the line I keep coming back to, in Shenzhen and again on other panels: the issue is not a shortage of principles, but a failure to apply them at the right moment: before a product ships, rather than after the harm has occurred.
Why review boards without teeth don't count
Most organizations doing "AI governance" well have some kind of ethics review process. The problem is what happens when that review actually disagrees with a launch decision.
The numbers here are more revealing than the rhetoric. EY's Technology Pulse Poll, fielded in February 2026 and published the following month, surveyed 500 US technology-industry business leaders at organizations with 5,000 or more employees. Only 50% said their AI governance or ethics leaders have full independent authority to halt high-priority or revenue-generating AI projects that fail established safety and ethical guardrails. Another 42% said such authority requires the intervention or approval of the board or CEO. Put plainly: in roughly half of these organizations, the people responsible for catching an ethical problem cannot act on what they find without escalating to the very executives whose revenue targets are at stake.
Two further findings put that in context. 85% said their organizations prioritize speed to market and iterative innovation. They manage regulatory and ethical risk as the technology evolves in the real world, rather than through exhaustive pre-launch vetting and full regulatory alignment. And 52% said department-level AI initiatives were operating without formal approval or oversight at all.
Read those figures with appropriate caution. The sample covers senior leaders at large US technology companies and relies on self-reported answers, so it shouldn't be generalized across industries, company sizes, or jurisdictions. It's also worth naming that EY sells AI governance and risk consulting, which gives the firm a commercial interest in findings that reveal governance gaps. But note which way the self-reporting bias runs: executives describing their own oversight are far more likely to flatter it than to understate it. If anything, 50% is a ceiling, not a floor.
A review that cannot stop or delay a launch is not real oversight. It only looks like oversight without actually having any power. That is the accountability gap, and it is the one most frameworks avoid naming.
The mechanism I've been arguing for has three parts:
Review while the design can still change. Run the ethics and safety assessment when the product is still being designed. Because at this stage, changing it costs a conversation, not a rebuild in later stage. This is also the cheapest possible moment to do it. A safety problem found at the design stage costs a meeting; the same problem found after launch costs a recall, a regulator, and a news cycle. Reviewing early isn't a tax on speed. It's how you avoid the delays that actually hurt.
Match scrutiny to risk. Most uses should clear review in days, not weeks. The team can use a short screening question set with no committee involved. Reserve full review for the genuinely high-risk cases: generating a real person's face or voice, decisions affecting someone's access to a job, a loan, or a public service, and anything involving children. Those get mandatory review every time.
Give the review function real authority and real accountability. Two things make this work, and both are structural rather than cultural. First, the reviewer must report to management outside the department that owns the product. A review function reporting to the same executive whose revenue target depends on shipping will not block a launch, no matter what its charter says. Second, a halt decision needs a defined appeal path involving a named executive or board committee, on a stated timeline, with the outcome recorded. A veto with no appeal is unaccountable power, and organizations are right to resist it. A veto with an appeal is a governance process: the launch can still proceed, but someone senior has to put their name on that decision. That's the difference between oversight and a suggestion box.
Setting the bar: what approval before launch actually contains
Saying "review before launch" is easy. Making it mean something is harder. Here are four requirements a product should meet before it ships, not after.
A mandatory AI ethics and safety assessment covering harms to users, not just harms to the company. Corporate risk registers typically track physical, financial, and reputational exposure, and those categories quietly exclude most of what actually concerns me, starting with child safety. A child groomed through a platform, a person denied a loan by a biased model, a community whose shared sense of what's true is eroded by synthetic media: none of these fit neatly into the standard three categories. So the assessment needs to name the others explicitly: harms to rights (privacy, autonomy, non-discrimination), psychological harms, and harms that fall on a group rather than on any single identifiable person. A register that only counts corporate exposure will miss the harms that land outside the organization, and it will miss them by design, not by accident.
Independent audits of output risk. Independence has degrees, and it's worth being precise about which one you mean. Independent of the product team is the minimum, and it's cheap. Independent of the business unit is meaningfully harder and matters more. Fully external audit is expensive and should be reserved for the highest-risk deployments. Moreover, don't limit this to harmful, explicit, or exploitative content. Content is the easy case. The voice-clone fraud I opened with isn't "harmful content" in any content-moderation sense, and neither is a lending model that quietly declines a whole postcode. Audit the outputs that carry consequence, not just the ones that look bad in a screenshot.
Clear accountability mechanisms requiring project owners to document and mitigate foreseeable misuse. Not all misuse is foreseeable. But a lot of misuse is foreseeable. If there's a written record showing someone already thought of the risk, "we didn't think of that" is no longer a valid excuse. Legal counsel will raise a fair objection here: documenting anticipated harms creates a discoverable record, and the natural instinct is to write less. That instinct is understandable but counterproductive, and the problem is a solvable one. Other safety-critical industries, from aviation to healthcare, protect internal safety analysis through defined legal privilege and confidential reporting channels, precisely so that honest hazard assessment is not punished. If an organization expects its engineers to think seriously about misuse, it must first make it safe for them to record that thinking.
Compliance with global and local regulations and standards. The conventional advice is to design to the strictest regime and let compliance flow downhill from there. I would push back on that, for two reasons.
The practical objection is that these regimes do not nest. They run in different directions rather than sitting at different heights on the same scale. China's PIPL requires certain data collected in China to stay there, with export gated by a government security assessment. The GDPR imposes no localization mandate at all, but restricts what may leave the EU and on what basis. Neither is the stricter version of the other, so "strictest" gives no answer in the case that actually matters.
The second objection is one of principle. Defaulting to the most demanding regime in practice usually means defaulting to whichever jurisdiction legislated first and loudest. That exports one region's assumptions about privacy, risk and the relationship between citizen and state into markets that did not choose them, and it removes local context from a decision that badly needs it.
The workable rule is to separate the floor from the ceiling. Meet a firm baseline everywhere you operate, treat it as non-negotiable, and above that floor comply locally and deliberately, documenting each difference between markets rather than ignoring it.
One rule I'd make automatic: any solution using sensitive data without a clearly stated usage purpose gets flagged high-risk and routed to governance review by default. Define "sensitive" concretely up front rather than leaving it to argument. For example, biometric and health data, data about children, and anything revealing race, religion, political views, or sexual orientation is "sensitive" in most countries. Exceptions should exist. Rules with no exception process do not produce compliance; they produce informal workarounds that are harder to see and harder to correct. But exceptions must be documented, time-limited, and subject to review, rather than granted informally. The point is not that no project ever receives an exception. It is that review is the default position, and an exception must be justified.
The critical thing is that none of this blocks innovation in adjacent fields. Dubbing, animation, accessibility tools all continue freely. What it blocks is shipping a high-risk capability with no one accountable for how it gets used.
Closing the risk chain at both ends
A pre-launch checkpoint catches what you can anticipate. It does nothing about what happens after the product is in the world, which is where most real misuse actually occurs. So the framework needs commitments on the other end too:
AI risk management training for employees and customers alike. Engineers and sales teams are not AI governance experts and should not need to be. What they do need is enough training to recognise the signals that something they are building or selling requires expert review, and to know how to escalate it. Customers need enough AI literacy to judge a service by what it discloses: whether AI use is labelled, whether consent was genuinely sought, and whether an automated decision can be challenged. They should treat these as entitlements rather than courtesies, and be willing to switch to a provider that meets them. Customer pressure of that kind reaches places internal governance cannot.
A mandatory governance checkpoint at every lifecycle phase: Business proposal, solution planning, development, verification, operation, maintenance. Not one gate at launch, but a recurring question at each stage where the design or deployment context changes.
Plain-language AI-use disclosure at every product launch. If a customer can't understand from the documentation what the AI does and where its limits are, disclosure has happened in a legal sense and not in any sense that matters.
Beyond that, I'd argue for a public incident registry which contains confirmed misuse cases and the remediation steps taken, published in the way a security transparency report is. It's uncomfortable, which is precisely why it works. An organization that has to publish its failures develops a strong institutional interest in not producing them.
Training at both ends closes the risk chain: catching issues before launch, and catching misuse after. Misuse gets caught by many eyes, not one checkpoint.
A note for anyone reading this from the policy side: most of what I've described is internal company architecture, and regulation can't sensibly dictate a firm's reporting lines. But it can require disclosure of them. A rule that obliges companies to state publicly who holds halt authority over high-risk AI launches, and where that person reports, would do more than another set of principles.
Same technology, different risk — so regulate the risk, not the tool
The question I get most often is where to draw the line between encouraging innovation and preventing misuse. Here's the reframe I use: the same synthetic media technology that clones a friend's face to steal millions can dub a public-health message into twenty languages that would otherwise never reach the people who need them. The technology is identical. The line falls not on the technology, but on the use and the risk it carries.
In practice, that means sorting uses into three bands rather than banning or blessing a whole category:
Low-risk (dubbing, animation, a reading voice for someone who is blind): continue freely.
High-risk (generating a real person's face or voice): allowed, but only with safeguards built in before launch, namely labelling the content, confirming consent, and keeping a named person accountable.
Over the line (impersonating a real person to deceive or defraud): blocked outright, no exceptions.
Regulate the tool instead of the risk, and you lose the accessibility voice and the inclusive translation along with the scam. Regulate the risk instead, and you keep the benefit while still catching the danger. Labelling and provenance, already called for under the G7 Hiroshima AI Process, let a genuine health video prove that it is real, while a scam cannot make the same claim. This is a light safeguard that supports innovation instead of blocking it.
There is no single standard that fits every market
My mother refused to let me install an AI fall-alert camera in her home. She valued her privacy more than she valued my peace of mind about her safety. That is one household, in one place. Now scale that diversity of values across the APEC region. Japan has taken a light-touch, promotion-oriented legislative route. South Korea has passed a comprehensive framework act. China regulates through a layered set of CAC measures with registration and labelling requirements. Singapore works through voluntary model frameworks and testing toolkits, and the ASEAN Guide on AI Governance and Ethics sits alongside all of it. Add different comfort levels with surveillance and different relationships between citizens and the state, and it becomes clear that a single global standard was never going to fit everyone.
The answer isn't to abandon standardization. It's to separate the floor from the ceiling: agree on a common baseline of non-negotiables covering labelling, disclosure, human accountability and child protection, then design deliberately for divergence above that floor. For a body like APEC, that means three concrete moves: a shared vocabulary for risk, so "high-risk" means roughly the same thing whether you're in Tokyo, Seoul, or Jakarta; a common baseline of safeguards that doesn't try to impose a single cultural standard; and interoperability, so testing, assurance, or reporting done in one economy can actually be understood and trusted in another.
The test I keep applying
Whenever I evaluate an AI governance proposal now, whether corporate or national, I ask the same question. If this system worked exactly as designed, would it have stopped the video call scam before the money moved? Consider what the answer depends on. A review board that can only advise. A definition of "high-risk" too vague to trigger mandatory review. No one holding the actual authority to say no. Where any of these is true, the answer is no, and the framework is decoration.
Accountability is what happens when someone is answerable before the harm, not after it's already scaled for years. That's a much higher bar than publishing a set of principles. It's also the only bar that actually matters.
Sources
EY, "Autonomous AI adoption surges at tech companies as oversight falls behind", Technology Pulse Poll, March 2026.